Sunday, 14 March 2010

Binary data and strings

Don't expose your bits in publicYou have no idea how often I get an e-mail that talks about binary data (for me, usually protobuf data) and string encoding (usually via utf-8).

Here’s the thing folks: most binary data cannot be translated to a string with a utf-* translation. It just isn’t possible. If you are talking about an arbitrary byte sequence that you need to store or transmit as a string, then your best bet is base-64.

Fortunately, in .NET Convert.ToBase64String and Convert.FromBase64String deal with all the details, making it trivial to use.

I keep talking myself into (and then back out-of) adding string-based overloads (etc) to protobuf-net; maybe I’ll add them just to stop the internal debate…

Sunday, 7 March 2010

The last will be first and the first will be last

I’ve probably mentioned that I’m currently re-writing some code using IL emit. Very interesting work, and I’ve learned a lot about the CLI in the process.

The work I’m doing at the moment works using the decorator pattern, giving each node the chance to manipulate the value, which is usually expected to be at the top of the stack.

The problem is… imagine we want to call:

someWriter.WriteInt32(theValueOnTheStack);

To call this, we need “someWriter” before the value on the stack (i.e. push “someWriter”, push the value, callvirt). There are two options at this point:

  • Change the calling code so that we already pushed “someWriter” earlier in the code (very problematic – it makes the stack very complex, especially considering branching etc)
  • Declare a local variable, store the value on the stack into the variable, push “someWriter”, push the value from the local variable, callvirt

Only the second is an attractive option, but in itself this causes me problems – not least in some code where this would lead to a lot of locals being declared (even though I have some fancy local pooling to re-use like-typed variables as far as possible; the problem is when lots of different types are involved).

So how about we change the API? As it happens, “someWriter” is easily available (as arg1 or arg2). What about if we made it a static method, and passed the instance in last?

SomeWriterType.WriteInt32(theValueOnTheStack, someWriter);

OK – this is a pretty freaky calling convention, but it fits our typical usage perfectly. Given that the value is already on the stack, now I just need to push “someWriter”, call (not callvirt). Obviously the ex-instance-method code needs changing – essentially the different between:
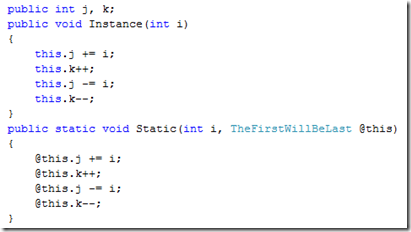
image

Note that it is important that I am not using “virtual” methods in all this, as that would demand the original usage.

But does it cause a performance problem? (note: yes I know this is all micro-optimisation, but I have a genuine reason for trying to minimise the stack size, which is the real purpose behind this).

So I fired up a typical test-rig that calls the methods an insane number of times:

image

The results aren’t necessarily surprising – simply confirming that this doesn’t have any negative impact on performance. It actually makes things slightly faster, but all I really needed to know is whether it would end up being 100 times slower or not. It isn’t. Not having the locals is my main aim.

So it looks like I’m going to end up with backwards methods. Which is fine – only my code will see it (it isn’t part of the user-facing API, although it does have to be public to allow for calling from other assemblies).

In this case, I can live with an odd calling convention ;-p

Friday, 26 February 2010

protobuf-net v2 on the iPhone

A basic iPhone application showing two fields with values in; there isn't much to see.

It might not look very impressive to you, but this is pure joy to me. It is the first evidence I’ve seen that the revised rewritten protobuf-net can work in MonoTouch for use on the iPhone – and presumably MonoDroid in the future.

A big thanks here to Christian Weyer and Andrew Rimmer who both offered some help here (since I don’t actually own a mac, an iPhone or MonoTouch!). The grab is from Andrew (he assures me it works fine on the actual device too).

This piece of work has been a slog, and I kept putting it off (because frankly, re-writing the entire stack is a huge job). The goals have not been trivial:

  • Continue to support all the existing runtime-only usage…
  • ..while also making it support fully static / AOT compatible
  • Allow it to write serialization dlls in advance (like sgen)
  • Fix the stability issues on Compact Framework (caused by overuse of generics)
  • Remove some performance bottlenecks on Compact Framework
  • Support POCO (or more accurately, work without requiring special [attributes]) so you can use it with types outside your influence, or for inheritance that isn’t known at compile-time
  • Make it work on iPhone etc
  • Make it even faster
  • Make it more extensible (for example, what if I want to write a proxy that writes a DataTable to a protobuf stream?)
  • Make it support mutable structs (yes I know that they are usually evil, but people simply keep asking for this, in particular for XNA)
  • Remove a heap of code-debt caused by an evolving project that grew without a 100% clear direction
  • Throw in some other feature-requests and bug-fixes for good measure
  • And as a side-benefit, it even compiles and runs on .NET 1.1 or via mcs on Mono (with minimal #if usage)

I should stress that it is not yet complete – but the core of the engine is there and working, demonstrating most of the key points above (albeit in a very raw state). There’s still a way to go, but it is getting there.

Saturday, 13 February 2010

Everything “is” an object?

This nugget of the .NET unified type system. And the cause of oh so much misunderstanding.

My way of looking at it is that it isn’t helpful to think of value-types (structs in C# parlance) “as objects”. You can treat them as though they are, but you need to fundamentally change them (box them) in order to do it. Which has lots of uses for sure; but just make sure you understand what you are doing and why. If a value-type truly was an object you wouldn’t have to do this.

It is a bit like saying all people are meat; technically true, but if you start manipulating me like you would beef, don’t expect me to be quite the same afterwards.

Instead, I try to emphasize that everything can be treated as an object.

Oh, and mutable structs are evil, but you already knew that.

Tuesday, 2 February 2010

New spike - looking hopeful

After a few false starts, I've finally found some time to spike the much-needed re-work for protobuf-net; this pretty much means "re-write it from scratch, learning from design mistakes and copying the occasional block of code".

Key changes / goals:
  • Generics: for the most part, gone from the guts of the implementation; it now uses a non-generic "decorator" approach - you wouldn't believe how much pain they have caused me (here)
  • This should hopefully fix compact-framework (here, here), and might (no promises at this stage) even allow it to work on .NET 1.1 and micro-framework
  • Build around a runtime model rather than attribute reflection (but with attribute reflection to be added as a model provider)
  • Much easier to unit-test individual decorators
  • Double implementation; vanilla decorator for "light" frameworks, and compiled implementation for the full-fat versions
  • I lack the hardware to test, but I'm hopeful that the vanilla decorators will work on iPhone - I don't suppose you have an iPhone and iMac to spare?
  • Potential to emit the compiled version to disk (think: sgen)
  • Added buffer-pooling (makes it possible to use a larger buffer with minimal allocation costs)
  • Re-written the string handling to use pointer (unsafe) code where appropriate, and better incremental encoder handling
There is still masses to do - but I'm feeling pretty happy with the initial results... I've got the core engine in place, and enough decorators to write some basic messages. Timings below, with meanings:
  • New (decorator) - vanilla decorator implementation - no optimisations (yet; although I'm sure we can improve this once I can tell what works/where)
  • New (compiled) - compile/flatten the decorators into a single operation
  • New (delegate) - same, but to a delegate rather than class (just for fun)
  • Old: the existing protobuf-net "generic" Serializer

   New (decorator): 3399ms
New (compiled): 788ms
New (delegate): 619ms
Old: 758ms
New (decorator): 2569ms
New (compiled): 642ms
New (delegate): 604ms
Old: 754ms
New (decorator): 2549ms
New (compiled): 631ms
New (delegate): 623ms
Old: 740ms
New (decorator): 2589ms
New (compiled): 640ms
New (delegate): 608ms
Old: 750ms
New (decorator): 2587ms
New (compiled): 638ms
New (delegate): 614ms
Old: 750ms
New (decorator): 2433ms
New (compiled): 519ms
New (delegate): 504ms
Old: 664ms
New (decorator): 2318ms
New (compiled): 512ms
New (delegate): 506ms
Old: 596ms
Oh, and I need to fix all the other things, too... sigh.

Thursday, 28 January 2010

Distributed caching with protobuf-net

No, this isn't my server farm.

I’ve been playing with distributed caches lately, and of course this is a really good use-case for something like protobuf-net – if there is anywhere you want to minimise your memory costs, network IO costs and CPU costs, it is your cache (it gets kinda busy).

As a pure example of “which system can I get installed and running the quickest”, I looked at memcached, using the windows service from here and the enyim.com client. Not only were they a breeze to get working, but this setup seems pretty popular, and also covers memcached providers, which uses enyim under the hood.

Fortunately, the enyim client has an extension-point that allows you to nominate a serializer through your config file (actually it calls it a transcoder, but I’m not sure it fits the definition). This allows us to swap BinaryFormatter for protobuf-net, which (for suitable types) has huge savings – in my crude tests I was seeing only 20% of the original network traffic, and roughly 75% of the original CPU costs.

Enough bluster…

OK, so in r282 I’ve added just such a transcoder (I still don’t like the name…) – and the good thing it is so effortless to configure it:

Before:

<enyim.com>
<memcached>
<servers>
<add address="127.0.0.1" port="11211" />

After:

<enyim.com>
<memcached transcoder="ProtoBuf.Caching.Enyim.NetTranscoder, protobuf-net.Extensions">
<servers>
<add address="127.0.0.1" port="11211" />

Wasn't that was painless? and some huge benefits (although obviously you’d want to run some integration/regression tests if applying this to an existing system). Oh, and of course you need to include protobuf-net and protobuf-net.Extensions.dll in your project, in addition to the enyim dll.

My only niggle is that because there is no way of knowing the type up-front, I had to include the outermost type information on the wire (hence the “Net” in the transcoder’s name, since it won’t be truly portable). I could get around this by having the caller indicate the type, but the enyim dll doesn’t play that game.

What next?

If you find it good/bad/pointless/buggy please let me know.

If you’ve got another cache that might benefit from some protobuf-net love, please let me know. Velocity, perhaps? Azure?

Monday, 4 January 2010

Reflections on Optimisation – Part 3, Fields and Properties

Short version:

Unless you are doing something interesting in your accessors, then for “full” .NET on classes, it makes no difference. Use automatically-implemented properties, and “commit”.

Much ado about nothing:

Previously, I discussed ways of modelling a general-purpose property accessor, and looked at existing APIs. So what next? I’m rather bored of conversations like this on forums:

OP: My flooble-gunger application uses public fields to hold the flipple-count, but I’m getting problem…

Me: back up there…. why does it use public fields?

OP: For optimisation, obviously!

But is there anything “obvious” here? I don’t think this is news to most people, but public fields are not generally a good idea – it breaks encapsulation, is (despite belief otherwise) a breaking change (and sometimes build-breaking) to swap for properties, doesn’t work with data-binding, can’t participate in polymorphism or interface impementation, etc.

With regards to any performance difference, you would expect that in most “regular” code, member-access does not represent the overhead. We would hope that the only times when member-access might be truly interesting is (like for me) if you are writing serialization / materialization code. Still, let’s plough on with this scenario, and check things out.

In particular, for simple properties (for example, C# 3.0 “automatically implemented properties”) our expectation is that they will commonly be “inlined” by the JIT. The big caveat here (where I might forgive you) is Compact Framework (for example XNA on XBox 360), which has a much weaker JIT.

So as before; let’s test it. Another very simple test rig, I want to compare (each in a loop):

  • Direct property access on an object
  • Direct field access on an object
  • A wrapper (as before) that talks to a public property
  • A wrapper (as before) that talks to a private property
  • (automatically implemented properties vs manual properties)
  • A wrapper (as before) that talks to a public field
  • A wrapper (as before) that talks to a private field

To achieve the private tests, I’ve created the wrapper implementation as a nested type of the object I’m testing. Oddly enough, there were some oddities that popped up, but I’ll discuss those next time; this post has been long enough, so here’s the very uninteresting result (sorry for the anti-climax):

Implementation Get performance Set performance
  • Prop, no wrapper
  • Field, no wrapper
  • Public prop wrapper
  • Private prop wrapper
  • Auto prop wrapper
  • Public field wrapper
  • Private field wrapper
6, 6, 29, 28, 29, 29, 28 25, 28, 52, 50, 50, 50, 50
(numbers scaled, based on 650M iterations, lower is better)

Both direct and via abstraction, the cost is identical for fields and properties. Quite simply – don’t stress over it.